On this page
Can AI Follow a 15-Second Video Prompt?
 Photo to Video
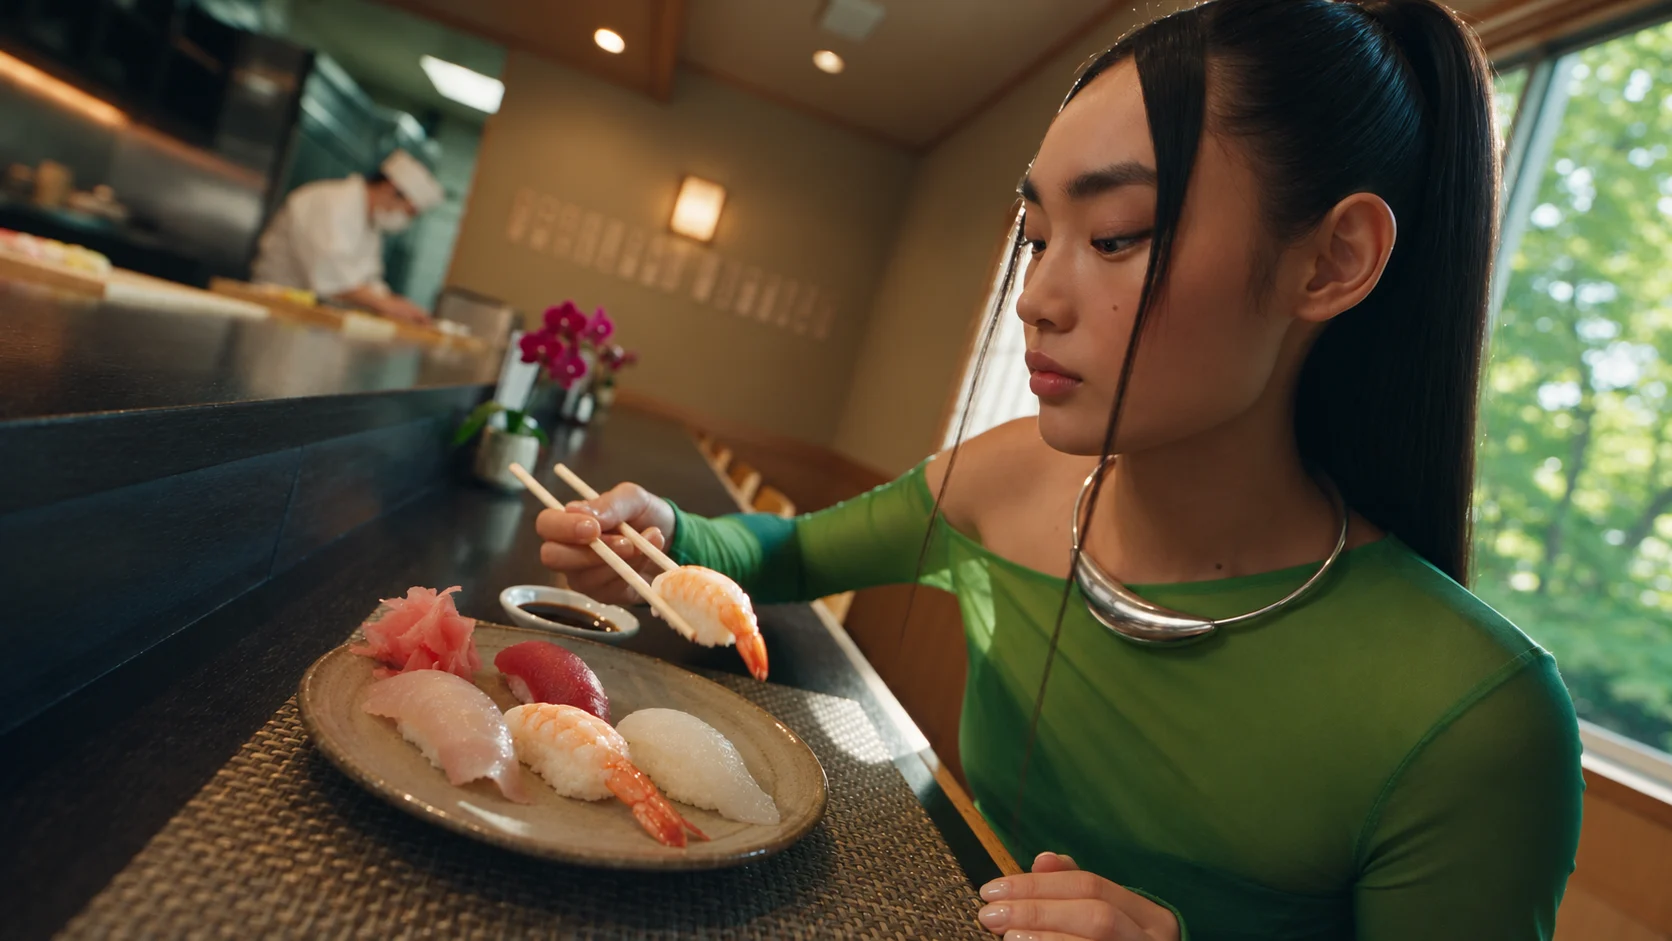
A detailed video prompt can specify a timeline: "0–1s she bites, 1–4s her face scrunches up, 4–8s…". But does an image-to-video model actually follow that timeline?
We tested it once on November 11, 2026 (UTC). One image, one 3,571-character prompt, three models on Photo to Video, all set to 15 seconds at 720p. Two models finished a video. The third rejected the request. On November 12, we added one Kling Pro run with the same image and unchanged prompt, at 1080p. It finished. Below are the full prompt, all three original outputs, and the dated follow-up observations.
Short answer: in the original 720p test, Wan and Seedance roughly followed the emotional order the prompt asked for (sour, then disgusted, then surprised, then happy), but neither carried out every instruction. Some actions came early or were left out, and one model moved the camera the opposite way to the prompt. For this kind of request, check both the event order and the timing instead of assuming the timestamps were followed.
The Kling Pro follow-up showed a prolonged sour reaction without a clear delighted finish. It used a different resolution and cost more; completing the request did not mean completing every requested action.
Watch the narrated comparison
Watch the comparison on YouTube
What we tested
The image. A user-supplied, AI-generated image of a young woman at a sushi counter, holding a shrimp nigiri with chopsticks. The source was supplied as a generated image, not a camera photograph. 1672×941.
Open the complete AI-generated source image (1672 × 941)
The prompt. 3,571 characters, sent unchanged to the three initial requests and the later Kling Pro request. It asks for one continuous handheld shot with no cuts, a tilted frame held for the whole shot, a camera that slowly moves closer to her face, and five timed beats:
| Time | What the prompt asked for |
|---|---|
| 0–1 s | She lifts a whole shrimp nigiri and puts it in her mouth in one bite |
| 1–4 s | Instant sour reaction: eyes shut, lips puckered, chopsticks clatter onto the plate, a fist lightly pounds the counter, she shakes her head |
| 4–8 s | Disgust: chewing slower, nose wrinkled, a slight gag, she lifts a napkin to her lips as if to spit it out |
| 8–11 s | She freezes, eyebrows jump, eyes open wide; she lowers the napkin an inch and chews, suspicious but intrigued |
| 11–15 s | Delight: eyes close, a big smile, she leans back, kicks her feet, hums, and reaches for the next shrimp nigiri |
The full prompt, word for word:
Read the complete 3,571-character prompt
Cinematic 15-second single continuous handheld shot, no cuts. A fictional young East Asian woman in her early twenties, entirely original character resembling no real person, model or existing film character: sleek black hair pulled into a high tight ponytail with two long loose strands framing her face, soft natural makeup with muted rose lips, a chunky polished silver collar necklace, wearing a vivid green sheer mesh long-sleeve top draped off one bare shoulder over a matching green top (original designs, no brand tags). LOCATION: a cozy daytime sushi bistro (fictional place) — a long polished dark-wood counter with a woven rattan runner, warm cream walls with blank decorative scroll banners bearing NO readable writing, soft glowing cabinet lights, an open kitchen blurred in the background with sushi chefs working, a red orchid in a pot, and a large window flooded with bright midday light and lush green trees outside, gentle teal-and-warm film color cast. In front of her: a ceramic plate of assorted sushi, a small dish of soy sauce, a mound of pink pickled ginger, wooden chopsticks in her hand — all plain and unbranded. COMPOSITION: she sits in the RIGHT THIRD of the frame, never centered, in three-quarter view facing the window light, the long counter and blurred open kitchen stretching away into the left two-thirds with shallow-focus depth; shot from slightly BELOW her eye line across the countertop, the out-of-focus sushi plate and woven runner cutting the bottom edge of the frame; the frame holds a constant dutch tilt of about 10-12 degrees, horizon never leveling. CAMERA: light playful handheld, breathing and swaying on the operator's elbows against the counter, micro-jitter, slow unsteady slide along the counter edge closer to her face as the shot progresses, window light softly flaring the lens, never static. ACTION AND EMOTION TIMELINE — the opening action happens AT SECOND ZERO and the first emotion detonates at FULL comic intensity immediately, no build-up: 0–1s in the very first frames she lifts a whole SHRIMP NIGIRI — pale pink butterflied shrimp on a rice pillow — with her chopsticks and shoves it into her mouth in one bite; 1–4s the sour hit of vinegared rice and ginger strikes INSTANTLY — her face implodes, eyes screwed shut, lips puckered hard around full cheeks, shoulders shuddering, chopsticks clattering down onto the plate, one fist pounding the counter lightly, ponytail whipping as she shakes her head fast; 4–8s the sour turns to open disgust — face going flat with revulsion, chewing slower and slower, nose wrinkled, gagging slightly, tongue pushing the bite to her cheek, she grabs a napkin and lifts it to her lips ready to spit it out, eyes betrayed; 8–11s with the napkin at her mouth she suddenly freezes — eyebrows jump, eyes pop open, the flavor has turned — she lowers the napkin an inch, chews once, twice, slowly, suspicious but intrigued; 11–15s pure delight blooms — eyes closing in bliss, a huge glowing smile spreading as she chews, she melts back on the stool, kicks her feet lightly under the counter, hums with pleasure and reaches with her chopsticks for the next shrimp nigiri, cheeks flushed in the window light. Shallow depth of field, 35mm film texture, warm teal-tinted japanese-indie-film grade, soft grain, cozy slice-of-life cinema look. No captions, no subtitles, no readable text anywhere — blank scrolls, blank menus, no signage — no logos, no brands, no mascot figurines or recognizable characters of any kind, fictional location, no real people, no copyrighted characters.
Download the exact submitted prompt
Original settings — November 11, 2026 (UTC).
| Setting | Wan Pro | Seedance 2.0 Mini | Kling Fast |
|---|---|---|---|
| Page | Wan | Seedance | Kling |
| Length | 15 seconds | 15 seconds | 15 seconds |
| Resolution | 720p | 720p | 720p |
| Sound | On (this tier has no sound switch) | On (no sound switch) | On (no sound switch) |
| Price on the button | 180 credits | 216 credits | 252 credits |
| Charged | 180 | 216 | 252, refunded the same second |
| Result | Finished in about 5 minutes | Finished in about 3.5 minutes | Request rejected about 1 second after submitting |
| Output | 1278×720, 30 fps, 15.0 s, with an audio track | 1280×720, 24 fps, 15.1 s, with an audio track | None |
One sushi-scene run per tested model variant. The November 12 Pro follow-up is listed separately below; it does not replace the Fast failure. The original files are presented unedited. The separate diagnostic length experiment described below is not part of this comparison.
Try a timed prompt with Seedance
Original 720p results
What happened in each time window
We stepped through both videos every half second and compared what we saw with each part of the prompt.
| Time | Wan Pro | Seedance 2.0 Mini |
|---|---|---|
| 0–1 s | Lifts the nigiri; it is at her mouth by about 1 s. | Opens wide and bites by about 0.5 s; eyes shut by 1 s. |
| 1–4 s | Eyes shut and cheeks puffed by 2 s. She sets the chopsticks down on the plate rather than dropping them, and raises a fist at about 4 s, but we did not see it hit the counter or a fast head shake. | Face scrunches up hard from about 1.5 s. The chopsticks are lying on the plate by 2 s. A raised fist from about 3 s; no visible hit on the counter. |
| 4–8 s | Frowning and chewing while looking down. She picks up a napkin around 7 s and holds it to her lips by 7.5 s. No clear gag. | Still mostly a sour, scrunched face rather than flat disgust. Napkin to her mouth around 7 s. Her eyes start to widen at 7.5 s, slightly earlier than the prompt asked. |
| 8–11 s | Napkin at her mouth until about 9 s, lowered at 9.5 s. Eyebrows lift and eyes open around 10 s; a small smile by 11 s. The "eyes pop open" moment is mild. | Eyes wide and eyebrows raised throughout. The napkin stays at her mouth until about 9.5 s, then drops below her lips around 10–11 s. |
| 11–15 s | Smiling with eyes closed around 11.5–12 s. She picks up the chopsticks and reaches for another piece from about 13.5 s. We did not see her lean back or kick her feet. | A big smile at 12 s, an eyes-closed smile at 13 s, then she picks up the chopsticks and reaches for the next nigiri at about 14.5 s. |
| Camera | Handheld movement throughout. From about 12 s the camera pulls back to a wider shot, the opposite of moving closer to her face, and the tilt is no longer clear. | Handheld movement, and the frame stays visibly tilted. The camera moves in during the middle and widens again near the end. |
What this shows. Both models put the emotional beats in the order the prompt asked for, and both ended with her reaching for another piece. The details are where they slipped: no clattering chopsticks or counter hit, a reaction that arrived early, a camera that moved out instead of in. Seedance's facial expressions were bigger and closer to the "full comic intensity" the prompt asked for. Wan's second half looked more like a calm, wide film shot.
We scanned every frame of both videos for sudden scene changes and found no obvious hard cut, but that does not fully prove each is one continuous shot. Both files have an audio track; we have not judged how the sound matches the prompt.
Kling Pro: November 12 follow-up
On November 12, 2026 (UTC), we submitted the same sushi image and the full 3,571-character prompt to Kling Pro (3.0 Pro), unchanged. This was one additional run, targeting 15 seconds at 1080p with sound. It completed in 279 seconds and cost 378 credits. The output is 1916×1080, 24 fps, 15.04 seconds, with an audio track.
Wan Pro and Seedance 2.0 Mini were tested at 720p, for 180 and 216 credits respectively. This is a same-image, same-prompt, same-target-duration comparison, not identical settings or a resolution-controlled quality ranking. These are dated test charges; check the current generation button before submitting.
| Time | Observed in Kling Pro |
|---|---|
| 0–1 s | Lifts the nigiri; it reaches her mouth around 1–2 s, later than the requested first-second bite. |
| 1–4 s | Bites and chews with puffed cheeks. The strongly scrunched, eyes-closed reaction comes later, around 6 s. |
| 4–8 s | Her face scrunches up and her eyes close. She sets the chopsticks back on the plate around 7 s rather than dropping them. No napkin appears. |
| 8–11 s | Raises a clenched fist during the continuing sour reaction. The requested napkin-lowering action is absent. |
| 11–15 s | A head shake around 11–12 s, then eyes and mouth open around 13 s. The mouth is closed again near the end. No clear delighted finish or reach for another piece. |
| Camera | The frame remains visibly tilted and ends closer to her face, consistent with the requested direction. This does not establish an exact 10–12° angle throughout. |
What changed: Pro completed the long prompt, but several action beats were delayed or missing. The concise result is: prolonged sour reaction; no clear delighted finish. We reviewed visual timing and key frames, not sound quality or lip sync. This single Pro result does not establish a general prompt-length limit, or test the separate 4K variant.
Why Kling Fast didn't produce a video
The Kling Fast request was rejected about one second after we submitted it. The provider's message was: "Request failed. Please check your input parameters and try again." The page showed that error straight away, and the 252 credits came back to the balance in the same second.
The message doesn't say what was wrong. In a separate length test with a different, neutral prompt (a fox in snow), on the same model with the same image, a 2,501-character and a 3,001-character version both produced videos, while the 3,571-character version failed with the same message. So prompt length is the most likely reason this sushi prompt was rejected. We did not find the exact limit, and we did not rerun the sushi prompt in a shorter form, so the failed Fast request gives no result for that variant's motion or image quality. The successful Pro follow-up above is a different model variant and resolution, not a shortened-prompt retry.
Pro accepted and completed the same 3,571-character sushi prompt. Do not generalize the Fast failure into a universal Kling limit: the exact limit for either endpoint was not established. Preserve the original when revising a prompt.
What to check in your next timed prompt
- Check the order and the exact second separately. In this test the broad sequence was recognizable even when individual actions were early or missing.
- Identify the actions you care about most. Check them explicitly rather than judging only the overall mood. This test did not compare different instruction orders.
- Check camera movement separately. Wan moved away near the end despite the requested move closer. We did not isolate why; simplifying the camera direction would be a new experiment.
- Check the result before building on it. Watch the whole clip, then step through it if timing matters.
- Watch the length. A very long prompt can be rejected outright by some models; see our prompt guide for shorter structures.
Limits of this test
- One image, one prompt, one run per variant: three original requests on November 11 and one Pro follow-up on November 12.
- All requests targeted 15 seconds. Wan, Seedance and the failed Fast request used 720p; the Pro follow-up used 1080p. No 4K test or matched-resolution Pro comparison was performed.
- The prompt was long and detailed; shorter prompts may behave differently.
- The Kling Fast result is a rejected request, not a quality result. Its diagnostic length test used a different prompt. Pro produced a video, but one success does not establish its maximum prompt length.
- The original two videos were checked at half-second intervals; the Pro follow-up used visual timing and key-frame checks. We did not judge sound or perform a continuous-shot audit of Pro.
- This is not a ranking of the models. For a side-by-side comparison of the same three models on a simpler prompt, see Kling vs Wan vs Seedance.
If a result looks soft or the person changes during movement, use our AI video blur checks to compare moving and still moments before spending credits on another attempt.
FAQ
Can AI follow a second-by-second video prompt?
Partly. In our test, Wan Pro and Seedance 2.0 Mini both followed the overall order of events but missed or moved some individual actions and camera directions.
How long can an image-to-video prompt be?
It depends on the model. Wan Pro and Seedance 2.0 Mini accepted our 3,571-character prompt in this test. Kling Pro also completed the unchanged prompt in a November 12 follow-up at 1080p. Kling Fast rejected it in the original 720p test. Separate length checks support prompt length as a likely cause, but we did not establish an exact limit for this endpoint.
How much did a 15-second, 720p video cost?
On November 11, 2026: 180 credits on Wan Pro and 216 on Seedance 2.0 Mini. Kling Fast quoted 252 credits; the request was rejected and the credits were refunded. Always check the price on the button.
How long did it take?
About 5 minutes for Wan Pro and about 3.5 minutes for Seedance 2.0 Mini, from submitting to the finished video. The November 12 Kling Pro follow-up took 279 seconds (4 minutes 39 seconds).
Which model followed the prompt best?
From one run each, Seedance's expressions were closer to the prompt, while Wan's camera ended wider than requested. Kling Pro showed a prolonged sour reaction without a clear delighted finish in the follow-up. It ran at 1080p rather than 720p. These single samples are not a general model ranking.
For shorter prompt structures, see our prompt guide. Plan paid attempts with the credit budget guide.